Rainfall Runoff Model Inputs#
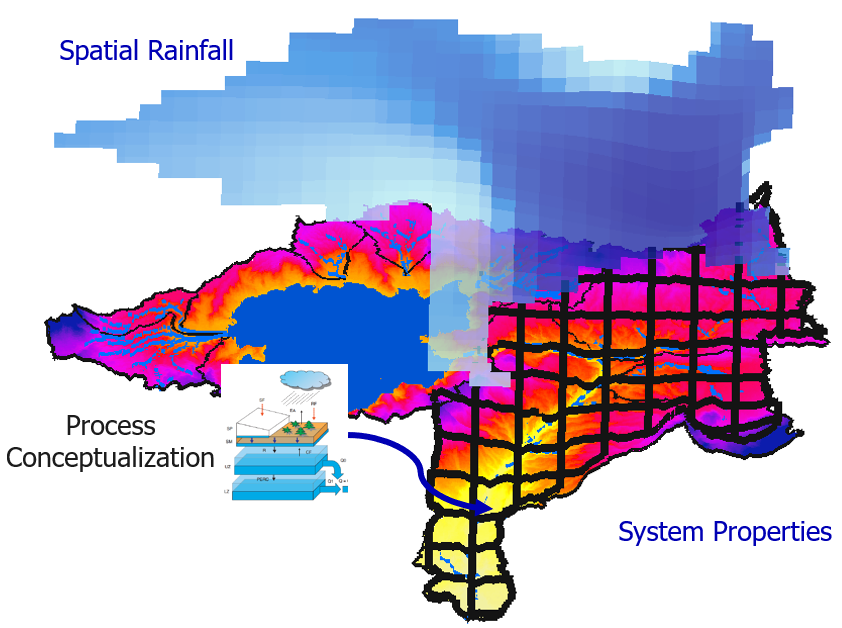
The required inputs for the distributed model is divided into Meteorological, GIS inputs and Distributed model parameters
Meteorological Inputs#
To be able to run the hydrologic simulation with Hapi the following meteorological inputs are required
- rainfall

- evapotranspiration

- Temperature
Distributed meteorological data can be obtain from gauge data with some interpolation method or from remote sensing data
Remote Sensing Data#
Remote sensing inputs are downloaded with earthlens, which replaces the
deprecated earth2observe package:
pip install earthlens            # CHIRPS and the other keyless backends
pip install earthlens[ecmwf]     # adds cdsapi, required for the ERA5 download below
Inside this repository the same dependency is the inputs extra, wired to the inputs pixi environment (the dev
environment on top of earthlens[ecmwf]), so the downloads below run without a separate install:
pixi run -e inputs python examples/hydrological-model/coello/prepare-Input-data/00-coello-data_download.py
earthlens exposes a single facade, EarthLens, that routes the request to the backend named by data_source. It
covers the sources Hapi used to handle, among many others:
- CHIRPS (
data_source="chc") — the Climate Hazards Group InfraRed Precipitation with Station data, a quasi-global rainfall data set combining satellite imagery with in-situ station data on a 0.05 degree grid, from 1981 to near present. Served over anonymous FTP, so it needs no credentials. - ERA5 (
data_source="ecmwf") — the Copernicus Climate Data Store reanalysis that replaces the retired ERA-Interim archive. It requires a free CDS account and a~/.cdsapircholding the Personal Access Token (see the CDS API instructions).
Rainfall from CHIRPS#
Passing variables as a plain list uses the global CHIRPS-2.0 series, and temporal_resolution selects the
dataset ("daily" → global-daily, "monthly" → global-monthly). The dict shape, e.g.
variables={"africa-pentad": ["precipitation"]}, reaches the rest of the CHC catalog.
from earthlens.core import EarthLens

EarthLens(
    data_source="chc",
    temporal_resolution="daily",
    start="2009-01-01",
    end="2009-02-01",
    variables=["precipitation"],
    lat_lim=[4.190755, 4.643963],
    lon_lim=[-75.649243, -74.727286],
    path="examples/hydrological-model/data/meteo_data/earthlens/prec",
).download(cores=4)
CHIRPS fetches one file per date, so cores runs the retrieval in parallel (without a progress bar). Each date is
clipped to the bounding box and written as <dataset>_<variable>_%Y.%m.%d.tif, for example
global-daily_precipitation_2009.01.01.tif.
Temperature and evapotranspiration from ERA5#
ERA5 variables are addressed by the (dataset, variable) pair, so variables is a dict keyed by the CDS dataset
name. Use the catalog to look up the codes:
from earthlens.ecmwf import Catalog

catalog = Catalog()
print(list(catalog.datasets))
catalog.get_variable("reanalysis-era5-single-levels", "2m-temperature")
Unlike CHIRPS, the ECMWF backend writes one NetCDF per variable rather than per-date rasters. Passing
aggregate=AggregationConfig(...) slices that NetCDF into per-date GeoTIFFs, which is the shape
Inputs.prepare_inputs expects:
from earthlens.core import AggregationConfig, EarthLens

root = "examples/hydrological-model/data/meteo_data/earthlens"

EarthLens(
    data_source="ecmwf",
    temporal_resolution="daily",
    start="2009-01-01",
    end="2009-02-01",
    variables={"reanalysis-era5-single-levels": ["2m-temperature"]},
    lat_lim=[4.190755, 4.643963],
    lon_lim=[-75.649243, -74.727286],
    path=f"{root}/netcdf",
).download(aggregate=AggregationConfig(freq="1D", op="auto", out_dir=f"{root}/temp"))
op="auto" reads the catalog's is_flux flag so each window gets the right reduction: state variables such as
2m-temperature are averaged, flux variables such as evaporation and total-precipitation are summed. Keeping
the NetCDF in its own folder leaves the GeoTIFF directory holding nothing else, since prepare_inputs reads a
whole folder at once.
ERA5 evapotranspiration is negative by convention — the meteorological convention is that downward vertical fluxes
are positive — so the values must be flipped before the model reads them. Dataset.apply(np.abs) does that; see
01-coello-prepare_inputdata.py in the prepare-Input-data examples.
Matching the file names when reading the rasters#
MeteoInputs.from_rasters locates the date in each file name with regex_string and parses it with
file_name_data_fmt, so the two must match the names the backend produced:
| Source | Example file name | regex_string |
file_name_data_fmt |
|---|---|---|---|
| CHIRPS | global-daily_precipitation_2009.01.01.tif |
r"\d{4}.\d{2}.\d{2}" (the default) |
"%Y.%m.%d" |
| ERA5 (aggregated) | 2m_temperature_1D_20090101.tif |
r"\d{8}" |
"%Y%m%d" |
The download example above takes rainfall from CHIRPS and the other two from ERA5, so the three folders do not
share a naming convention — r"\d{4}.\d{2}.\d{2}" finds no date in ..._20090101.tif, and r"\d{8}" finds none
in ..._2009.01.01.tif. Pass the differing argument per folder with per_variable, which is merged over the shared
arguments for that folder only:
model.meteo = MeteoInputs.from_rasters(
    prec_path,
    temp_path,
    evap_path,
    per_variable={
        "temperature": {"regex_string": r"\d{8}"},
        "evapotranspiration": {"regex_string": r"\d{8}"},
    },
)
file_name_data_fmt is not needed here: it is inferred from the first name regex_string matches, per folder. Pass
it only for a layout the digits cannot settle, such as a day-first 03.02.1990.
When all three folders do come from one source, the shared arguments are enough:
model.meteo = MeteoInputs.from_rasters(prec_path, temp_path, evap_path)
Packing the rasters into NetCDF#
A folder of per-date GeoTIFFs is the slowest thing the model can be driven from: every run re-opens every file. Packing each driver once turns that into a single read, and the calendar travels inside the file instead of living in the file names.
from hapi.inputs import MeteoInputs

MeteoInputs.raster_folder_to_netcdf(prec_path, "prec.nc")
MeteoInputs.raster_folder_to_netcdf(temp_path, "temp.nc", regex_string=r"\d{8}")
MeteoInputs.raster_folder_to_netcdf(evap_path, "evap.nc", regex_string=r"\d{8}")

model.meteo = MeteoInputs.from_netcdf_files("prec.nc", "temp.nc", "evap.nc")
It takes the same reader arguments as from_rasters, so start / end convert a window
rather than the whole folder, and it refuses to write a file whose steps carry no dates —
a NetCDF with no time axis cannot be checked against the model's date range later.
On network storage, pass gdal_env to skip GDAL's per-open directory listing:
MeteoInputs.raster_folder_to_netcdf(
    temp_path, "temp.nc", gdal_env={"GDAL_DISABLE_READDIR_ON_OPEN": "EMPTY_DIR"}
)
That listing is a remote round-trip per raster — 369 ms against 18 ms over one 14,823-file
folder. It is not the default because disabling it also stops GDAL finding .aux.xml, world
files and .ovr sidecars.
One file for all three drivers#
The three single-variable files can then be merged, which names each variable after its driver so a reader asks for it by name rather than guessing at whatever the band was called:
MeteoInputs.combine_netcdf_files("prec.nc", "temp.nc", "evap.nc", "meteo.nc")

model.meteo = MeteoInputs.from_netcdf(
    "meteo.nc",
    precipitation="precipitation",
    temperature="temperature",
    evapotranspiration="evapotranspiration",
)
Once the rasters are downloaded, prepare them for the model with hapi.inputs.Inputs, which aligns every raster to
the catchment DEM — see GIS inputs and Parameters.